
 Install from Microsoft Store
One folder of scans, one file to send
You signed a lease page by page, scanned each sheet separately, and now four PDFs sit in your downloads folder in no particular order. Before you can email the landlord, you need one file, in the right sequence, with a single filename that makes sense in a thread full of attachments. That reordering-then-combining step is exactly what Local PDF Toolkit exists for, and it runs entirely inside the tab you're reading this in.
The same problem shows up in reverse. A colleague sends a ninety-page vendor contract when you only need the pricing appendix on pages 74 through 81. Extracting those eight pages by hand usually means opening a desktop PDF editor you don't have installed, or trusting a random web converter with a document that has your company's terms in it. This tool covers both directions, assembling scattered pages into one document and pulling a slice out of a longer one, without a server ever seeing the file.
Merging pages in the order you choose
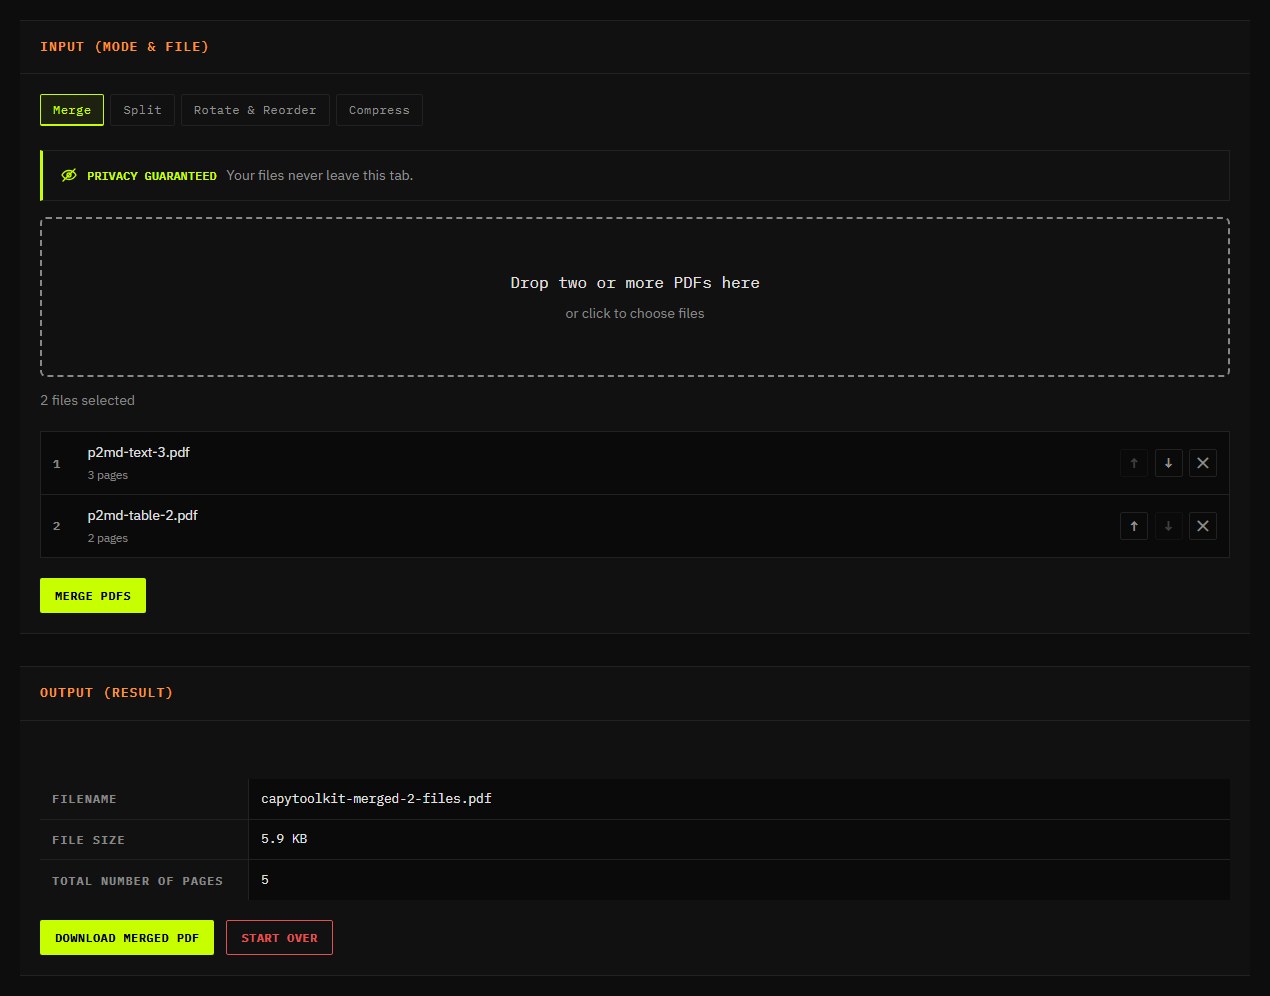
Merge accepts two or more PDFs at once, whether you drop them onto the dropzone or select them through the file picker. Each file lands in a list with its filename and page count, and you drag the rows into the exact sequence you want the combined document to follow. Because the reordering happens before anything gets written, you can rearrange a five-file bundle as many times as you like without waiting on a single re-encode.
Why page copies beat printing to PDF
Clicking Merge PDFs runs pdf-lib's page-copy routine against every file in that list order, one after another, and hands back a single PDF with a running page count so you can confirm nothing dropped out.1 Copying a page this way preserves its original content stream rather than rasterizing it into an image, so text stays selectable and vector graphics stay sharp in the merged file.2 That's a meaningfully different operation from printing every page to a virtual PDF printer, which flattens whatever it touches.
Splitting a long document into the ranges you need
Split works on a single loaded PDF and a plain-text field where you type the pages you want, using a syntax like 1-5, 8, 10-12. As you type, the tool checks each entry against the document's actual page count and shows a live list of what it's about to produce, catching a typo like a range that starts after it ends before you ever click Extract pages.
Each range becomes its own downloadable file rather than one shared archive. A shared ZIP would need its own compression step inside the worker, and most people extracting a single exhibit or chapter just want that one PDF, not an archive to open first. Request three ranges from a ninety-page contract and you get three separate downloads, each named after the original file and the page range it contains, ready to attach individually wherever they need to go.
Fixing page order, orientation, and stray pages
Rotate & Reorder is built for the PDF that's almost right: a scanner fed one sheet upside down, someone stapled the pages out of order before scanning, or a cover sheet you don't need got swept in with everything else. Loading a file here renders every page as a thumbnail using pdfjs-dist, so you're looking at the actual content, not a generic page icon, while you decide what needs to change.3
Dragging, rotating, and deleting pages
Drag a thumbnail to a new position, click its rotate control to step through 90-degree turns, or click delete to drop a page entirely, and the grid updates immediately so you can see the new sequence before committing to it. Saving sends that final order, along with each page's rotation and any deletions, through pdf-lib's page-copy pipeline in a background worker, and the rebuilt PDF downloads with your changes applied and nothing else touched.1
Compressing without a fake quality slider
Most PDF bloat comes from embedded photos and scanned pages, not from the text layer, so Compress targets those images directly instead of offering a generic quality percentage that doesn't map to anything concrete. The tool walks the PDF's internal object list for images encoded with DCTDecode, the JPEG compression PDF viewers already expect, decodes each one once, and keeps that decoded bitmap as the untouched source for every attempt that follows.4
Working through the compression ladder
From there it works through a fixed ladder of scale and quality combinations, redrawing each image through an OffscreenCanvas before re-encoding it, from a light pass at full size down to a more aggressive redraw at reduced dimensions, checking the resulting file size after each step and stopping the moment one fits your target.5 A live counter tracks progress through that ladder, so a large, image-heavy PDF doesn't leave you staring at a frozen button. If every step still lands above your target, usually because the PDF is mostly text with little image weight left to reclaim, the tool returns the smallest file the ladder produced and says so plainly instead of quietly flattening your pages into a blurry image to force a smaller number.
Before running the ladder at all, Compress checks whether your file already fits the target you picked from the four presets, 500 KB, 2 MB, 5 MB, or 10 MB, or a custom value you type in kilobytes or megabytes. When the original is already smaller than that number, the tool skips the redraw step entirely and hands back the same bytes you loaded, since there's nothing to gain from re-encoding a file that already meets the goal.
Every operation happens on this device
None of these four modes ever send your file anywhere. Merge, Split, Rotate & Reorder, and Compress all run pdf-lib's structural work inside a dedicated Web Worker, so the heavy lifting for a large scanned contract doesn't freeze the tab while you wait, and the bytes you loaded stay put.6
The worker exists only to keep the interface responsive; it has no outbound network request built into its job. Thumbnails for Rotate & Reorder render on the main thread with pdfjs-dist instead, because drawing a page preview is cheap enough not to need a worker, and both paths read the same in-memory bytes you dropped in rather than a copy fetched from somewhere else.3 Close the tab when you're done, and nothing about the document you worked on persists anywhere outside your own downloads folder.
- 1.
"pdf-lib," pdf-lib.js.org, accessed September 2026. https://pdf-lib.js.org/
- 2.
Peter Wyatt, PDF Association, "Parsing PDF's Dialects," pdfa.org, October 2023. https://pdfa.org/parsing-pdfs-dialects/
- 3.
Mozilla, "pdf.js," GitHub, accessed September 2026. https://github.com/mozilla/pdf.js
- 4.
ITU-T, "T.81: Information Technology - Digital Compression and Coding of Continuous-Tone Still Images," itu.int, accessed September 2026. https://www.itu.int/rec/T-REC-T.81/en
- 5.
Tim Dresser, "OffscreenCanvas: Speed Up Your Canvas Operations with a Web Worker," web.dev, December 2023. https://web.dev/articles/offscreen-canvas
- 6.
WHATWG, "Web Workers," HTML Living Standard, html.spec.whatwg.org, accessed September 2026. https://html.spec.whatwg.org/multipage/workers.html